Executive reading · ~60 seconds
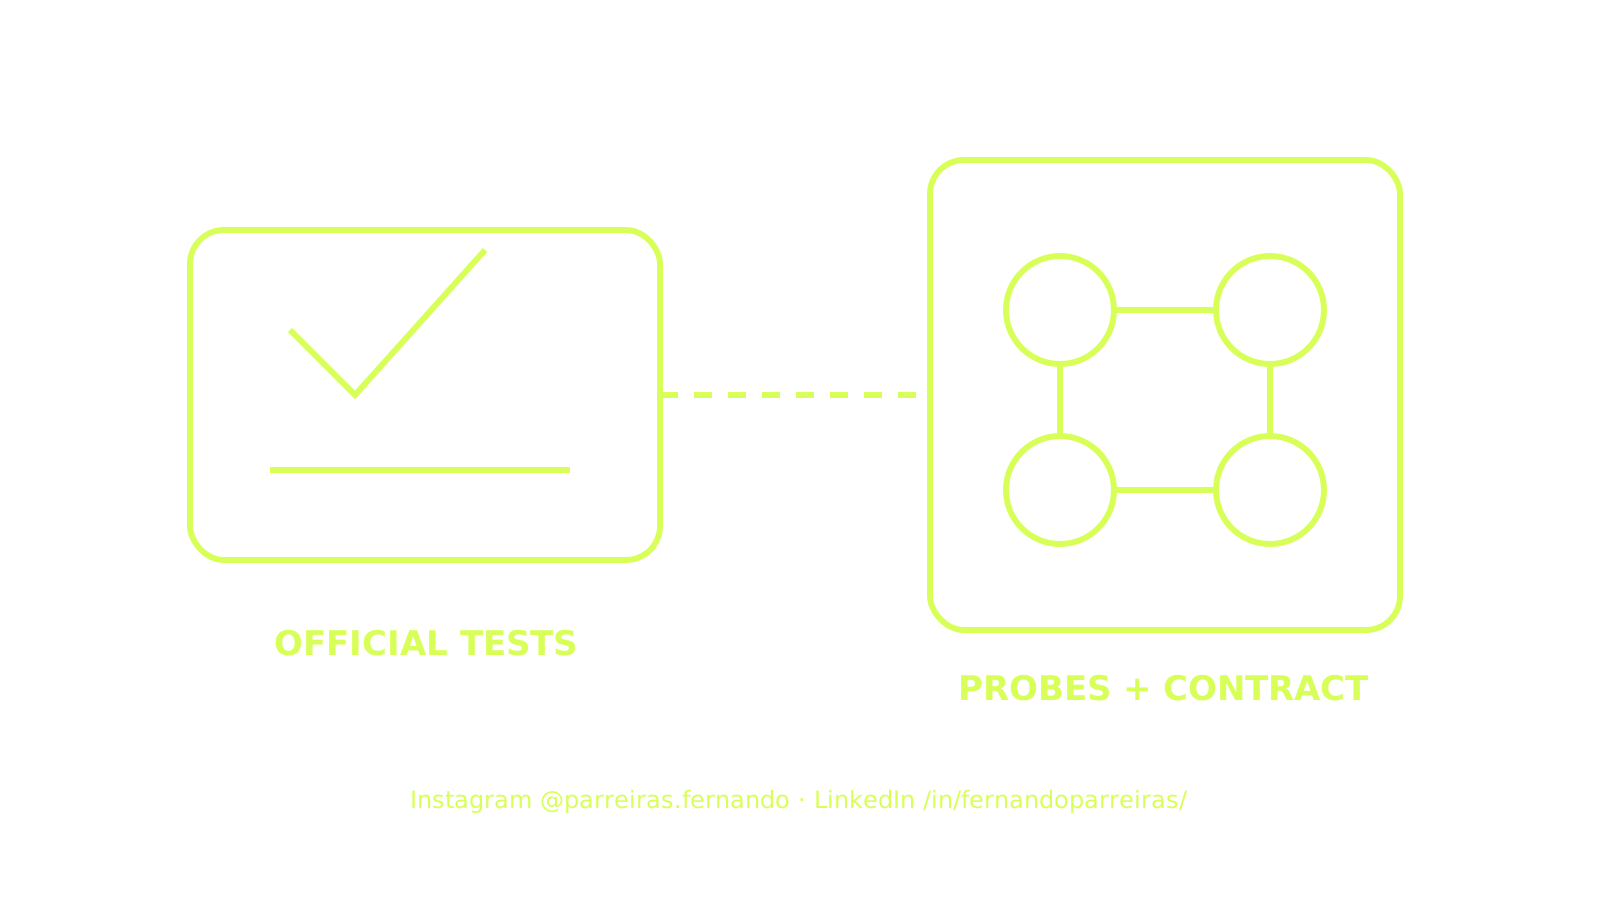
In InfraDev, hidden probes rejected 32% of submissions that passed the official tests. The benchmark contains 36 tasks from three projects, selected from 21,389 PRs; the result shows an acceptance gap, not a universal test-failure rate.
A change to AI infrastructure may compile, pass the project's tests, and still fail to deliver the requested numerical gain or distributed behavior. InfraDev turns this gap into a benchmark: real Megatron-LM, vLLM, and verl tasks accompanied by hidden probes that check interfaces, multiple GPUs, and requirements the original tests do not observe.
Status: Evidence Brief approved for publication. Editorial series: Papers we read for you. This text analyzes the InfraDev preprint. Trustyu did not reproduce the benchmark or verify the results on its own infrastructure.
36 tasks selected from 21,389 pull requests
The authors started with 21,389 pull requests and manually selected 36 tasks across three projects: Megatron-LM, vLLM, and verl. Twenty tasks require multiple GPUs. According to the paper, the reference change touches an average of 17.4 files and 1,818 lines.
This funnel produces deep tasks relevant to the study, but not a random sample of the 21,389 PRs. The source number describes the screened universe; the experimental denominator remains 36.
The official test did not represent the whole request
In 24 of the 36 tasks, the existing tests contained no explicit numerical assertion. Among 15 optimization changes, 13 did not verify whether the promised performance or resource savings had occurred. This does not mean the official tests were useless. It means their acceptance contract did not cover the stated goal of the change on its own.
The benchmark's hidden probes rejected 32% of submissions that had passed the official tests. This percentage applies to submissions generated under the study conditions and to the synthesized probes; it is not a universal false-positive rate for open-source project tests.
With the original request, no task was solved
When agents received only the original PR description, the paper reports zero solved tasks. With prompts reconstructed to declare interfaces called by the probes without revealing the solution, the best result reached 38.9% under the evaluated conditions.
The result shows that specification and evaluation form a pair. A probe may require something the agent did not receive as a requirement; an overly detailed prompt may reveal clues to the answer. The authors try to balance this boundary by building both together.
Domain knowledge changed the result without solving everything
For Megatron-LM tasks, a skill with structured knowledge increased the reported rate from 42.1% to 52.6%. That is a gain of 10.5 percentage points in that slice. It does not show that any instruction file produces the same effect, nor does it fully separate knowledge, format, and integration with the scaffold used.
An acceptance contract for optimizations
| Requirement | Proposed evidence | Failure the official check may not detect |
|---|---|---|
| functional behavior | output and invariants in valid and adversarial cases | plausible implementation that ignores a condition |
| numerical gain | baseline, metric, tolerance, and repetition | correct code without measurable savings |
| distributed execution | observed topology, versions, seeds, and synchronization | success on one GPU that fails on several |
| resource consumed | memory, time, communication, and cost under bounded load | shifting the cost to another stage |
| promotion | artifact digest, probes, limits, and decision | approval of bytes different from those evaluated |
The table is a professional proposal derived from the gap exposed by the paper. It was not evaluated as an intervention in the study and must be adapted to the system.
How to apply this without turning probes into a magic secret
- write observable requirements before choosing the implementation;
- preserve public tests for fast feedback and independent probes for acceptance;
- make the prompt declare every interface the evaluator will call without revealing the solution;
- validate the optimization against a baseline and tolerance, not only the absence of errors;
- reproduce the relevant topology or explicitly state what remained untested;
- separate functional failure, unavailable environment, timeout, and inconclusive result;
- bind the decision to the same artifact and dependencies that were verified;
- review probes when the contract changes and retain cases that prove rejection of an inadequate delivery.
In the Forge canon, specification, environment, tests, and evidence are parts of the harness; a green result does not replace the promotion boundary. This principle is a design guideline, not proof of adoption or effectiveness in a particular deployment. [HARNESS31-C2]
Limitations, affiliations, and conflict of interest
The benchmark includes 36 manually selected tasks from three projects and evaluates six models. Probes and prompts were synthesized with agent assistance and reviewed through the process described by the authors. The design improves observability of omitted requirements, but probes may also contain assumptions or favor a specific formulation.
The paper reports authors affiliated with Tencent Hunyuan and other institutions listed in the record. There is a direct professional interest in infrastructure and models. At the editorial cutoff, we found no complete independent replication. The abstract states that code, data, and environment will be released; the promised complete artifact was not found during this review.
The percentages measure the models, scaffold, budgets, prompts, hardware, and versions used in the study. They do not estimate team success rates, total deployment cost, security, or production quality.
Engineering rule
The existing test answers the contract it implements, not the intention someone imagined. If the goal is to reduce memory, improve throughput, or preserve distributed behavior, the condition must exist as an observable requirement and as acceptance evidence. Compiling and passing the suite is the beginning of the proof, not its end.
Direct sources
- InfraDev — arXiv record. Version, authors, abstract, and date.
- InfraDev — full text. Method, selection, results, ablations, limitations, and affiliations.
Editorial and responsibility note
This text combines facts attributed to sources with the author's analysis and technical proposal. Personal and professional viewpoints are not proven facts; numbers, denominators, population, method, affiliations, and limitations are identified when available. The content is informative and does not replace technical, legal, regulatory, or security assessment. InfraDev, Tencent Hunyuan, Megatron-LM, vLLM, verl, models, and cited institutions belong to their respective owners; there is no sponsorship or endorsement. Tech Human and Trustyu commercially provide digital product development and governance. Research, structure, and writing were assisted by AI; Fernando Parreiras authorized the topic, factual self-review, and publication on 29 October 2026, without additional independent human review. The preprint remains under observation, and this analysis may be corrected if a new version, artifacts, replication, or relevant challenge emerges.
Research cutoff: 29 October 2026. Editorial status: special Evidence Brief authorized for 3 November 2026 at 09:00 BRT.
Editorial and responsibility note
- Research cutoff
- Last review
- Recorded corrections
- No corrections recorded.
The cutoff above applies to the canonical claims. Additional sources and their access dates are identified in the article body.
This article combines cited sources, analysis, and the author's professional experience. Verifiable data and factual statements are linked to their respective sources. Interpretations, hypotheses, projections, recommendations, and opinions represent the author's professional point of view at the time of publication; they do not constitute proven facts, a promise of results, or legal, financial, or technical advice applicable to a specific case. Consult the original sources and qualified professionals before making decisions.
Claims and sources
HARNESS31-C2
A durable harness should maintain session history, orchestration policy and execution isolation as explicit boundaries, while adapters and plugins prevent model or channel choice from becoming the security boundary.
Limit: The sources show two implementations, not a neutral interoperability standard. Actual permissions must be independently enforced and tested outside model choices. This is a source-bound design input; it does not prove product adoption, operational maturity, independent attestation, search ranking, AI citation or outcome.
- Anthropic — Anthropic, proprietary-site-terms
- YC Software —YC Software, MIT
- YC Software —YC Software, MIT